Your Evals Test the Dataset. Production Tests the Agent.
An offline eval tells you how your agent handles the cases you thought of. Online evaluation policies score what actually happened — sampled from live traffic, on a schedule, with the failures surfaced rather than averaged away.
Sep 21, 2026 · Upendra Bhandari · Evaluation
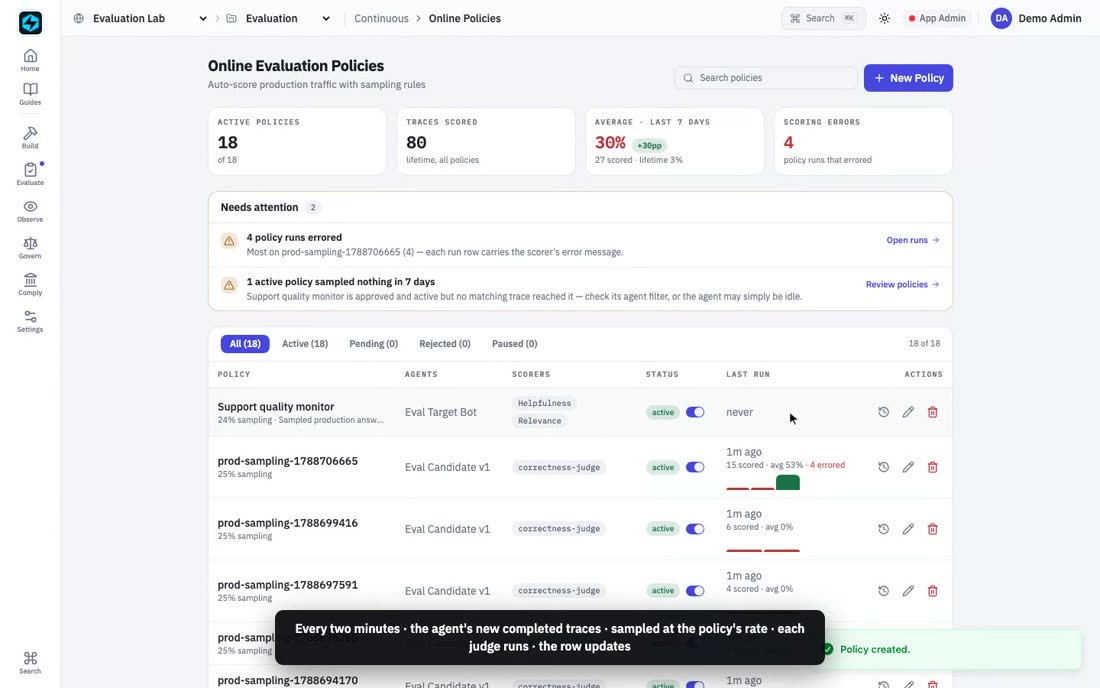
An offline eval suite tells you how your agent handles the cases you thought of. It says nothing about the customer who phrased the question a way nobody anticipated, at 2am, three weeks after you last ran the suite.
Online evaluation policies close that gap. You pick the agents to watch, the scorers to run and a sampling rate, and from the moment you save, production traffic gets scored continuously.
Auto-scoring live traffic
Three details in there matter more than the feature itself.
The average is a rolling seven days, not a lifetime mean. A lifetime average is a place regressions go to hide: months of good scores will absorb a bad week long past the point where you needed to know about it.
A check that could not run is an error, never a zero. If the judge times out or the provider is down, that run is marked errored and scores nothing. Silently recording it as a failing score would be worse than not measuring at all — you would be reacting to an outage in your own tooling as though it were a defect in the agent.
A policy that sampled nothing gets flagged. A monitor watching no traffic looks exactly like a monitor seeing no problems. The one that has matched nothing for seven days is called out, so a broken agent filter cannot pass as a clean bill of health.
Offline evals gate the change. Online policies watch what the change actually did.
 {{ meta.author }}