Your Labels Already Know the Better Prompt
A support-triage agent is live and quietly wrong, and nobody wrote a bad prompt. The house rules live only in how the support leads label tickets. Here is the loop that gets them out of the labels and into production, from traces to a shipped prompt, with one SDK.
Oct 11, 2026 · Upendra Bhandari · AutoLLM · SDK
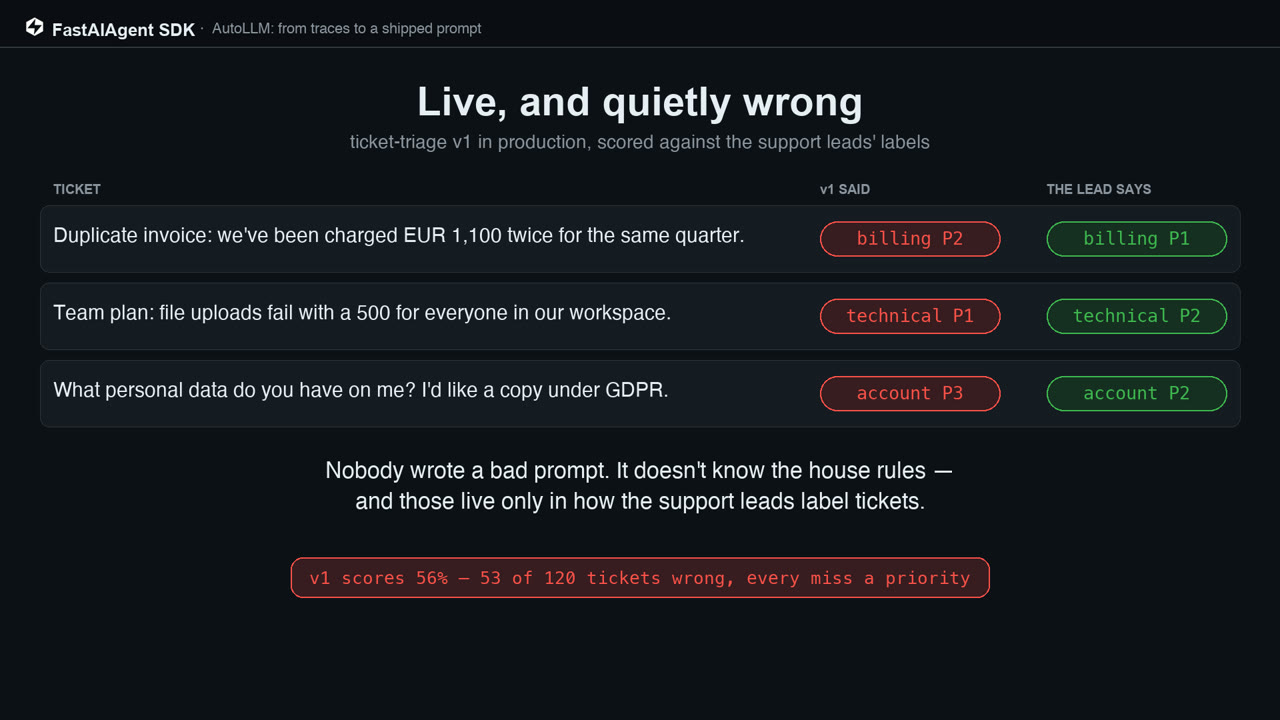
A support-triage agent is live, and it is quietly wrong. A EUR 1,100 double charge is filed as "soon". A Team-plan outage is marked urgent. A GDPR request sits at normal priority.
The problem: the prompt does not know the house rules
Nobody wrote a bad prompt. v1 has the five queues, the priority scale and the output format. What it lacks are the house rules: a billing dispute over EUR 500 is urgent, an outage is P1 only on Enterprise, a GDPR request goes to account at P2.
Those rules are in no document. They live in how the support leads label tickets. Scored against those labels, v1 gets 56%, and every miss is a priority.
The usual fix is a rewrite from a hunch, shipped on a hand test. The rules stay tacit, and the next prompt guesses at them again.
The solution: a loop that writes the prompt from the labels
Seven stages, one SDK.
Traces come stamped with the prompt version that produced them, so one call turns them into a dataset with the leads' labels as the expected answers. An eval then puts a number on what is live.
AutoLLM reads the failures with their labels and writes a better prompt. Every candidate is a real eval run, kept only if it beats the best, then checked on thirty tickets the search never saw: 0.63 to 0.97. The winner is registered as v2, plain text beside v1. Read the thresholds it recovered before you ship it.
The gate is plain pytest in CI: a pass bar, and no regression against v1. 96% on all 120 tickets, 51 fixed, 3 worse, each one named. Going live is one alias move, no deploy, and every trace stays linked to its version.
The proof is six new tickets the loop never learned from. v1 gets two right. v2 gets all six.
Run it yourself for about $0.30: the AutoLLM Closed Loop example in the SDK.
 {{ meta.author }}